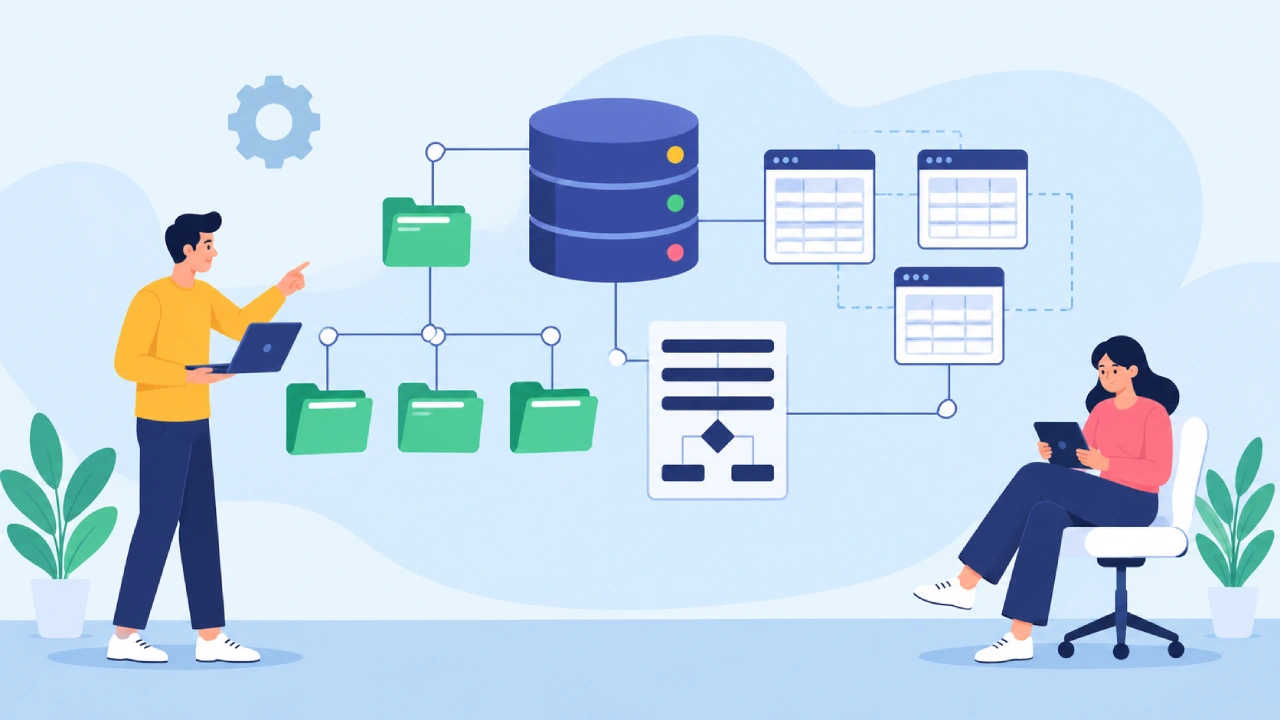
A well-built schema is central to a stable backend. As an app grows, the database must handle more data, more accounts, more reads and writes, and more linked records. If the schema was rushed, these changes can become messy. Teams can run into repeated records, rows that do not line up, slow queries, and extra logic added to fix it.
Database schema work is about deciding how data should be laid out in a database. For backend teams, that means picking tables and columns, setting up the links between them, and choosing keys and rules. It also means watching how the database behaves as the system gets bigger. The aim is not only to keep data. It is to set it up so the backend stays manageable as usage increases.
Tables and What They Do
In a relational database, tables hold data in rows and columns. A table usually stands for one main thing or one clear kind of information. For instance, an online shop often keeps separate tables for customers, items, purchases, and billing details. When you design a schema, you start by spotting the key entities in the app. A customer table should not mix in product details.
Those items are not the same kind of data, and they serve a different role. Putting each entity in its own table helps people read the data model. It also makes future updates less painful. It can also cut down on repeated values. Rather than saving the same customer info again for every purchase, the system stores the customer once. Then it links that customer record to each purchase.
Choosing Columns and Types
Once the tables are set, the backend team picks which columns each table needs. Each column should have a job to do. It should also use a data type that matches what it will store.
For example, a customers table might include an ID, name, email, and the date the account was created. Picking the right types helps block wrong input. It can also change how well storage and queries work. You also decide what must always be filled in and what may be blank. An email address often needs a value, while a short bio may be optional. Making these calls at design time avoids confusion later.
Primary Keys and Unique Rows
For most tables, you need a dependable way to tell rows apart. That job is done by a primary key. A primary key points to a specific row inside one table. Sometimes it is just one field, like user_id. Other times you use more than one field. This is a composite key, and it can fit better than a single column. Database engines treat the primary key as the rule for uniqueness.
They also use it to find rows faster. Names alone are not always enough. Two people can share the same name, but their user IDs still stay different. Then an app can store a safe reference to a user, instead of relying on data that might later change.
Table Links and Relationships
Real systems do not keep everything in separate boxes. Tables usually need to relate to each other. One-to-one is the rare case where one row maps to one row in another table. More often you see one-to-many. A single customer can place many orders. Each order, though, still belongs to only one customer. Then there are many-to-many relationships. Here, one side can link to many on the other side.
An order can include several products. A product can show up in many orders. To handle this, you create a junction table, like order_items. That table keeps the pairs and ties the two sides together. PostgreSQL also shows this pattern in its docs. It explains that multiple foreign keys can be used to model many-to-many links.
Foreign Keys and Referential Integrity
Foreign keys matter because they create actual connections between tables. A foreign key can be set so its value must exist in the related table. With a NOT NULL constraint, the database will not accept missing required data. A CHECK constraint limits values to what fits a given condition.
Keeping the schema easy to read
Speed matters, but it is not the only goal. The schema should also stay clear as more people join the team and the app gets bigger.
When naming stays consistent, it saves time. If table links are obvious and rules are applied in a clear way, developers do not have to guess. In PostgreSQL, schemas can act like namespaces too. That means you can group database items and keep them apart. Also, do not skip documentation. Teams should save entity relationship diagrams, or similar notes, so everyone can see the main tables and how they connect.
Final Thoughts
Database schema design is not a one-time step. It is a decision that affects engineering for years. A schema lays out where the data lives. It also sets the rules for how pieces fit together. Constraints help keep the data correct over time. Avoid copying the same values in many places. Add constraints when they actually prevent bad data. Do not stop at tables and links. Plan for indexes early. Look at how queries will run in real use. Think about how the data may grow. Also plan how you will change the schema later without breaking everything.
(Source)